The Graph Your Tools Can't See
Every codebase has two layers. The first one is what your current tools can see: import maps, call graphs, architecture diagrams, structural coupling, which imports what, which service calls which API, third-party package dependencies, and which test breaks when a module changes.
The second layer is invisible. It's the web of design decisions hiding between the lines of code, connecting components that have no structural relationship at all. Fifteen files with scattered inference calls, zero imports between them, no shared interface. A dependency analyzer sees nothing. But they're tightly coupled by a single architectural choice that one person made months ago and never documented.
Without understanding that second layer, you're not refactoring, you're guessing. And guessing makes things worse.
Every mature codebase is full of these landmines - a temporary workaround that calcified into production. A "DO NOT UNPLUG" sticky note on a cable that nobody remembers connecting. A flag that looks like dead code but is actually holding together a payment flow. Without the reasoning, you can't tell which constraints are load-bearing and which are dead weight. You either tiptoe around everything or break things you didn't know mattered.
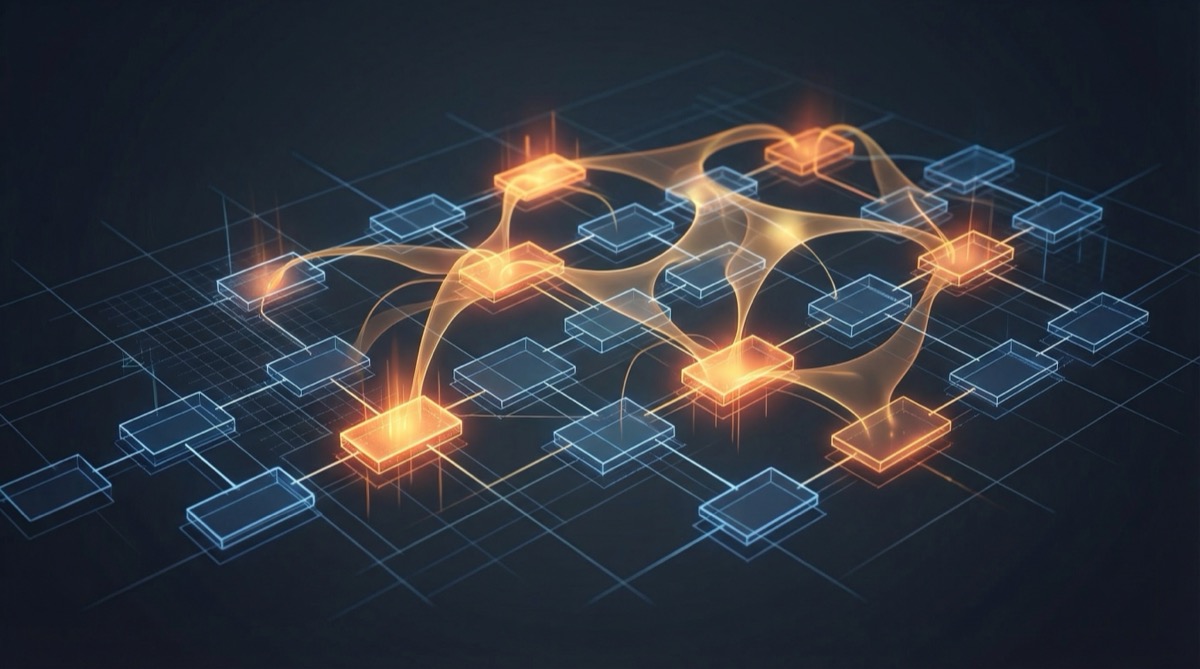
I think of it as a knowledge topology - a graph where nodes are components (files, services, APIs, critical configurations) and the edges are design decisions and reasoning chains that connect them semantically rather than structurally. Two nodes are connected not because a code module imports another, but because understanding one requires understanding the same design decision that shaped the other. A node is "hot" when someone's reasoning is load-bearing at that node and hasn't been captured.
Conway's Law (Melvin Conway, 1968) says organizations produce architectures that mirror their communication structures. The failure mode here is that undocumented decisions create invisible couplings that no communication structure can navigate, because nobody knows they need to. The team had the communication structure. What they didn't have was any signal that fifteen files were semantically coupled through a single eight-month-old trade-off. The knowledge topology isn't a map of people. It's a map of the product, like an fMRI scan of every design decision that shaped it. The team will eventually dissolve. The topology outlives them, because it's a property of what they built, not who they were.
Not every component carries equal knowledge risk, and this is where the flat "distribute knowledge" model breaks down.
Risk at a node concentrates through three mechanisms, all operating simultaneously. Semantic centrality - a Kubernetes config with twelve environment variables can be the reasoning-gateway to an entire payment flow. A feature flag in LaunchDarkly can carry a design decision that affects six downstream services. Lines of code and commit count are almost useless as proxies. The relevant question is how many other components require understanding this component's reasoning before you can safely change them? In network analysis, betweenness centrality measures how often a node sits on the shortest path between other nodes. The same concept applies here, and the hot nodes aren't always the biggest services. They're often the smallest, most-constrained pieces of the system, the ones where a single design constraint propagates far.
Knowledge concentration is the second mechanism. Cataldo and Herbsleb's 2013 research showed empirically that gaps between coordination requirements and actual coordination patterns significantly increase software failures. When the architecture requires understanding to coordinate, but the team's communication doesn't cover that understanding, failures compound. The node where only one person holds the theory is the node where that gap is widest. Ten contributors to a file don't close this gap if none of those contributions touched the original design constraint.
The third mechanism is the decay rate itself. A hot node where the reasoning was captured two years ago and never revisited has decayed toward uselessness, even if the original reasoner is still employed. Fritz et al.'s 2010 work showed that interaction information, not just authorship, determines knowledge score, and the negative effect of other authors contributing to a file is measurable. But reasoning behind design decisions isn't reinforced by code interaction at all. You can commit to a file a hundred times without ever touching the constraint that shapes why it's structured the way it is.
Departure looks like the primary threat, but that framing is wrong. The engineer who made the inference routing call was still on the team, committed to adjacent code regularly, yet the reasoning decayed because nothing ever forced him to re-engage with it. Eight months of other decisions, forty other trade-offs. The theory was already gone before he left. It had been decaying the whole time he was still at his desk.
A departure of an expert is the obvious threat. Decay while business-as-usual is the invisible one.
A node that scores high on all three (many semantic dependencies, single knowledge holder, reasoning that hasn't been reinforced in eighteen months) is the node that will cost you a full day when someone touches it.
Previously, I introduced event-driven capture - catch reasoning at the moment of decision, within 24-48 hours, while it's still original rather than reconstructed. But every team also has a backlog. Decisions that were never captured, some of them on hot nodes, all of them on a decay clock. Event-driven capture handles the flow going forward, but it doesn't touch the stock.
I call this microcapture - a short, structured recovery of reasoning before it decays past the point of recall. Not a documentation sprint, and not an ADR template with twelve sections. A 20-minute async conversation with the engineer who made the call, asking what alternatives were on the table and why this one. The output is a paragraph, linked to the relevant code, capturing the constraint that shaped the decision. Done while the original reasoner is still on the team and the decay is still recoverable.
Most teams have no system for this at all. Event-triggered capture is achievable in a sprint. But the real leverage is making topology-guided microcapture routine, hot nodes reviewed and refreshed before they decay past recovery.
Identify your three to five hottest nodes and run a microcapture before the end of the quarter. Sounds like a clean prescription, and the self-aware version of this advice has to acknowledge that identifying those nodes requires exactly the judgment that most teams don't have a systematic way to exercise. You need to know your topology to use it.
Without tooling, the identification process looks like a conversation. Pull the people who've been around longest. Ask them which components they'd be nervous to have a new hire touch unsupervised before they'd been walked through the reasoning first. That list is your hot-node approximation. That's imprecise, but better than waiting until the next refactor turns into a day of archaeology.
In practice, start with one question at a team meeting. Which five components would you be most nervous about if the person who designed them couldn't remember why they're built that way?
For each one, ask who holds the theory and when that person last explicitly re-articulated why it's built the way it is. If the answer is "I don't know" or "more than a year ago," that node is decaying and you know which direction to move first.
Run a microcapture on each one before the end of the quarter. Async works better than synchronous, for the same reason I wrote about last time. Synchronous sessions create social pressure that causes engineers to smooth over the uncertainty and unresolved edge cases, which are exactly the parts that matter most to preserve. A structured Slack thread, a Loom with a timestamped transcript, or written notes from a 20-minute call. The questions are 1) what were the alternatives you considered, 2) what constraint drove the choice, and 3) what would change the decision if circumstances shifted. Not what was built, because the code answers that. What did you think.
Do this quarterly, because the topology changes as the codebase evolves. New hot nodes emerge when systems grow and the original reasoners' attention moves elsewhere. A component that was well-understood six months ago becomes a hot node when the person who held its theory gets pulled onto something new for two sprints and then can't quite remember the specifics of the original constraint.
For that team, an hour of code cost a full day because nobody had a map of where the relevant reasoning lived, who held it, or when it had last been touched. You don't need wiki pages, a process owner, a budget allocation, or a documentation sprint. You need a diagnostic habit - monitoring, but for your reasoning topology.
Which node, in your codebase, would cost you the most to reconstruct if the reasoning disappeared tomorrow?
Next time: Once you can map where reasoning concentrates, the next question is what drives the decay rate at those nodes. Turnover is the obvious answer and not the most actionable one.